01The challenge
Machine learning engineers don't read marketing prose. They look at latency percentiles, GPU utilization, and cost per million tokens.
Competing against giants on raw silicon efficiency
Every AI infrastructure company claims to offer 'blazing fast inference'. But when enterprise teams evaluate inference platforms for production GenAI applications, they benchmark with real model weights: Llama 3, Mistral, Stable Diffusion, and custom embeddings.
SimpliSmart's proprietary software engine delivered lower latency and higher throughput than well-funded competitors like Together AI and Fireworks AI. However, their brand didn't reflect that elite technical reality. Our mission was to bring that raw engineering credibility directly to the surface.
What generic AI infrastructure sites do
- Nebula backgrounds and sci-fi gradients with zero technical relevance
- Vague claims of '10x faster' without reproducible benchmarking methodology
- Overly conceptual copy that frustrates senior ML engineers
- Hiding API documentation and hardware utilization specs behind contact forms
What SimpliSmart does
- Reproducible latency graphs comparing p50, p90, and p99 response times
- Detailed software compiler breakdown: memory paging and kernel fusion
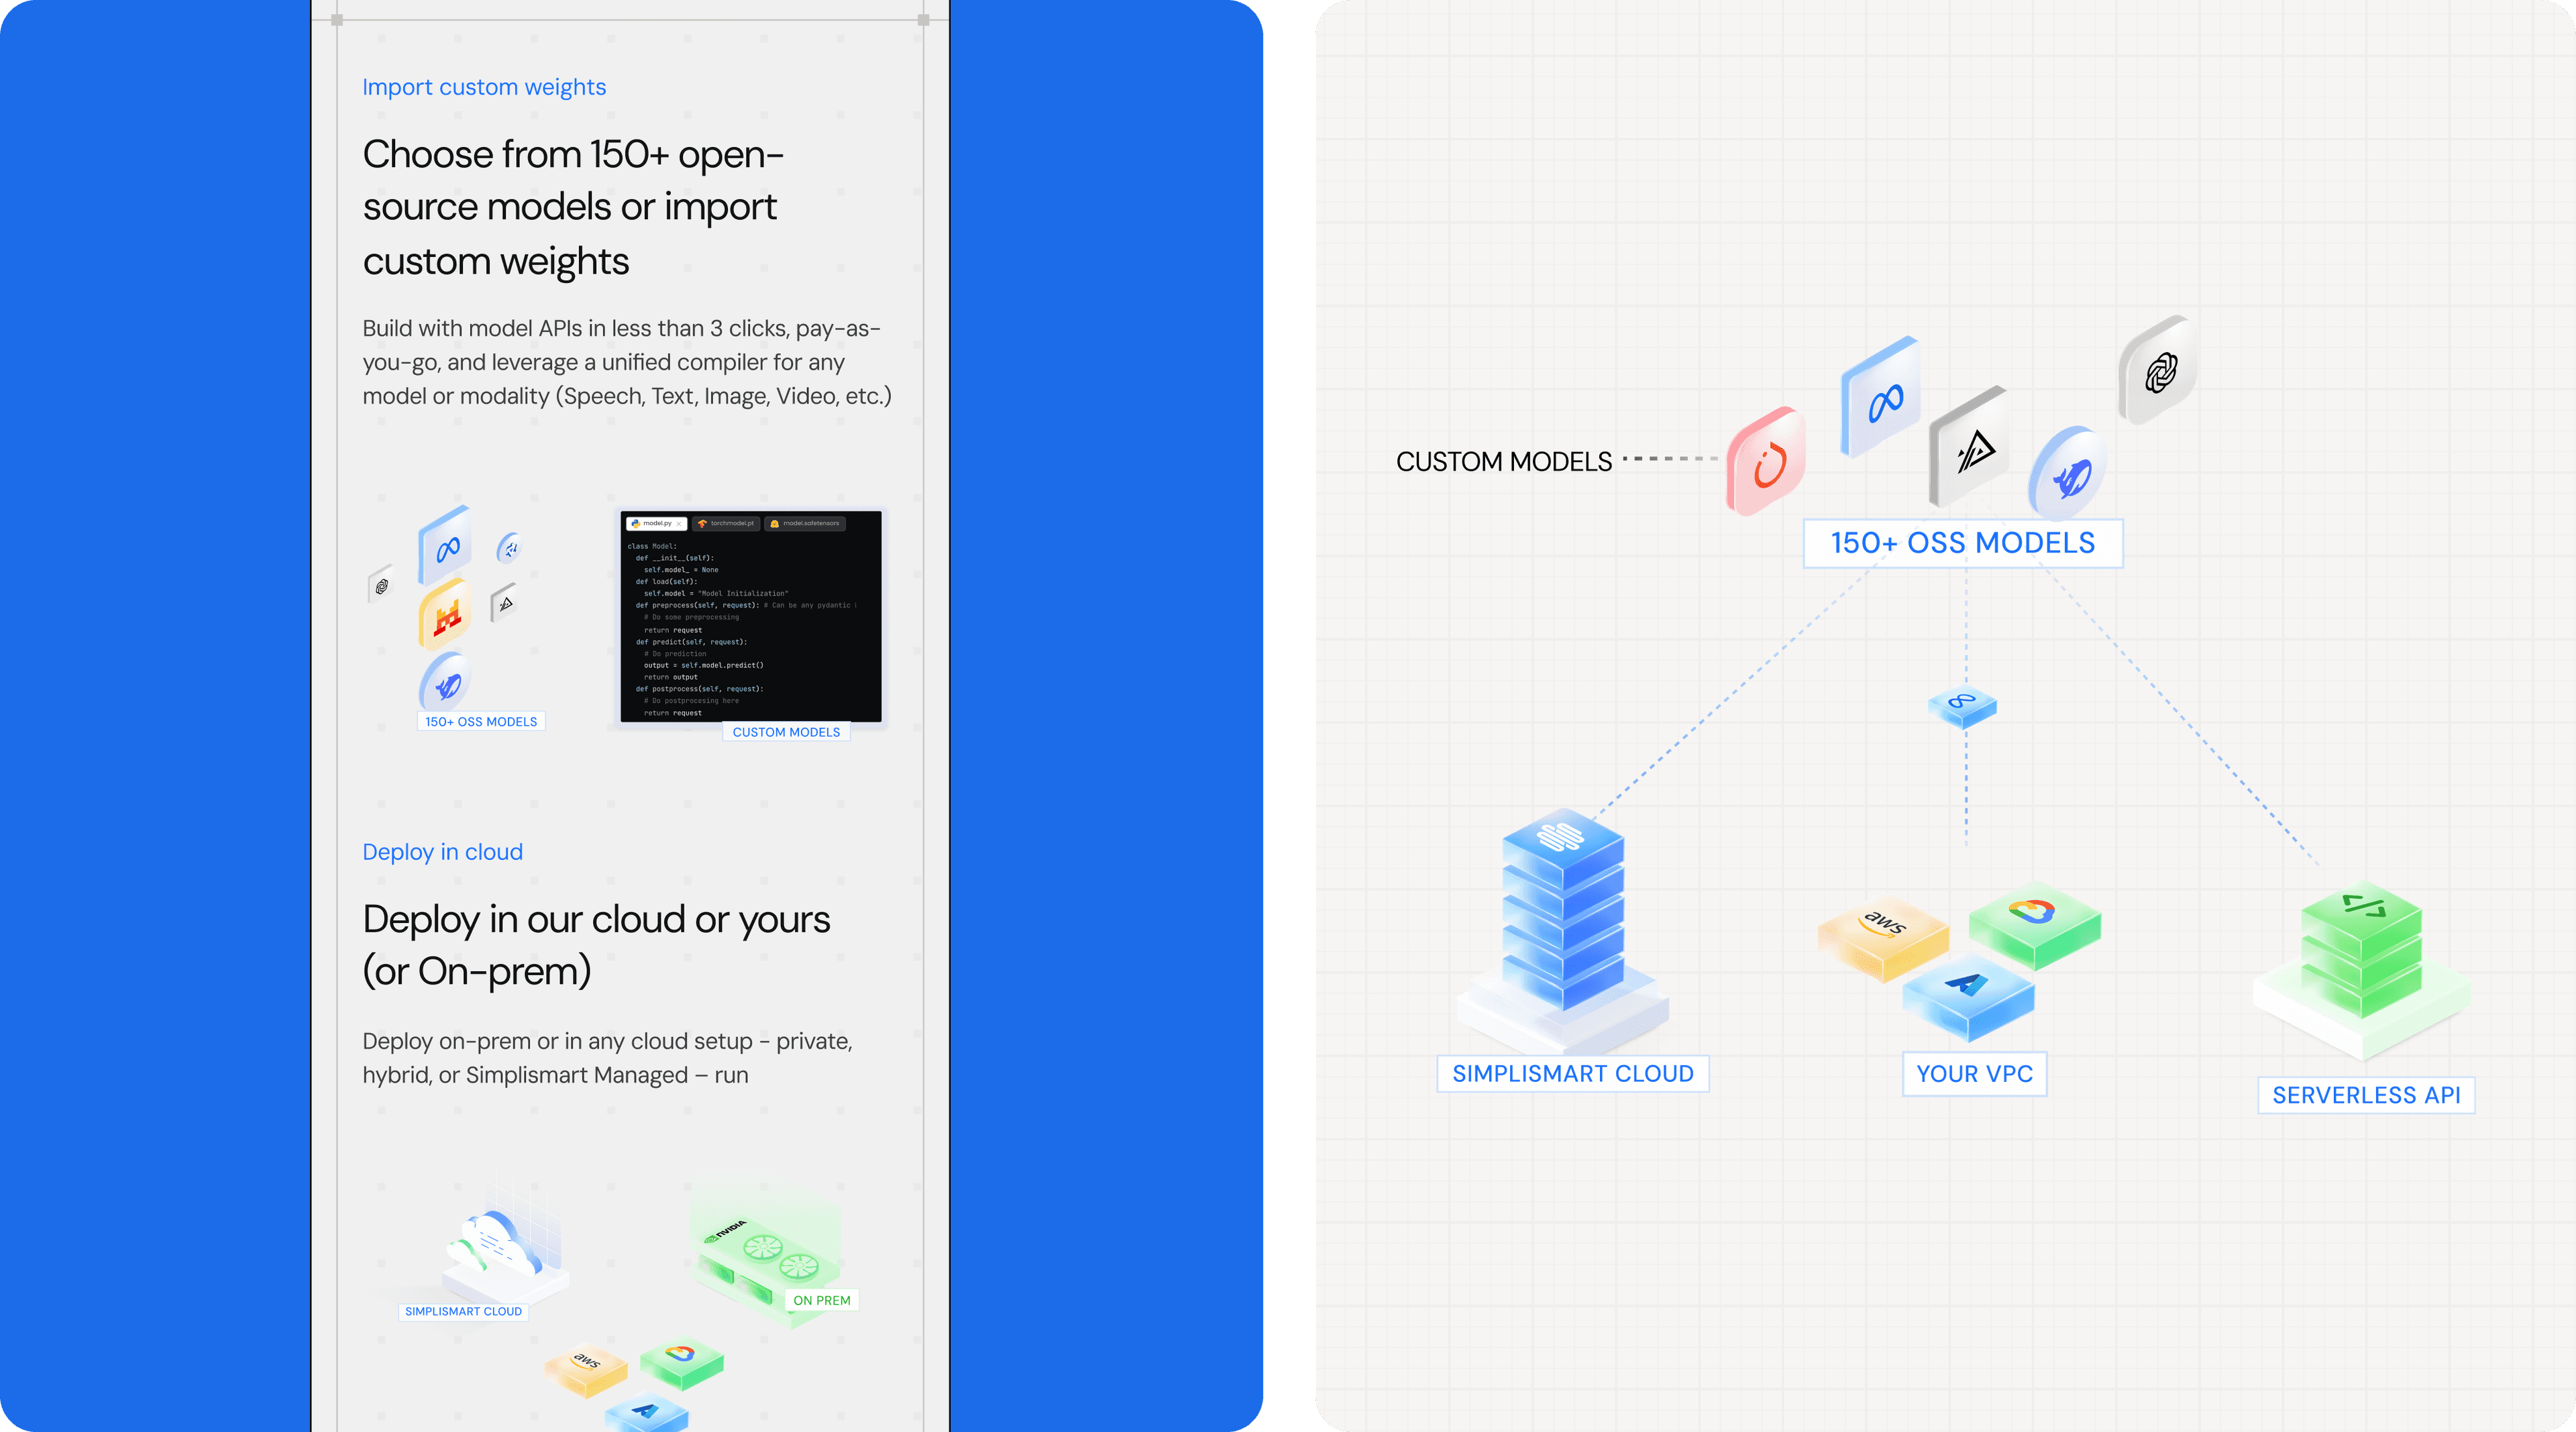
- One-line Python SDK integrations with interactive terminal snippets
- Technical cobalt color science signaling precision cloud engineering
02The architecture of speed
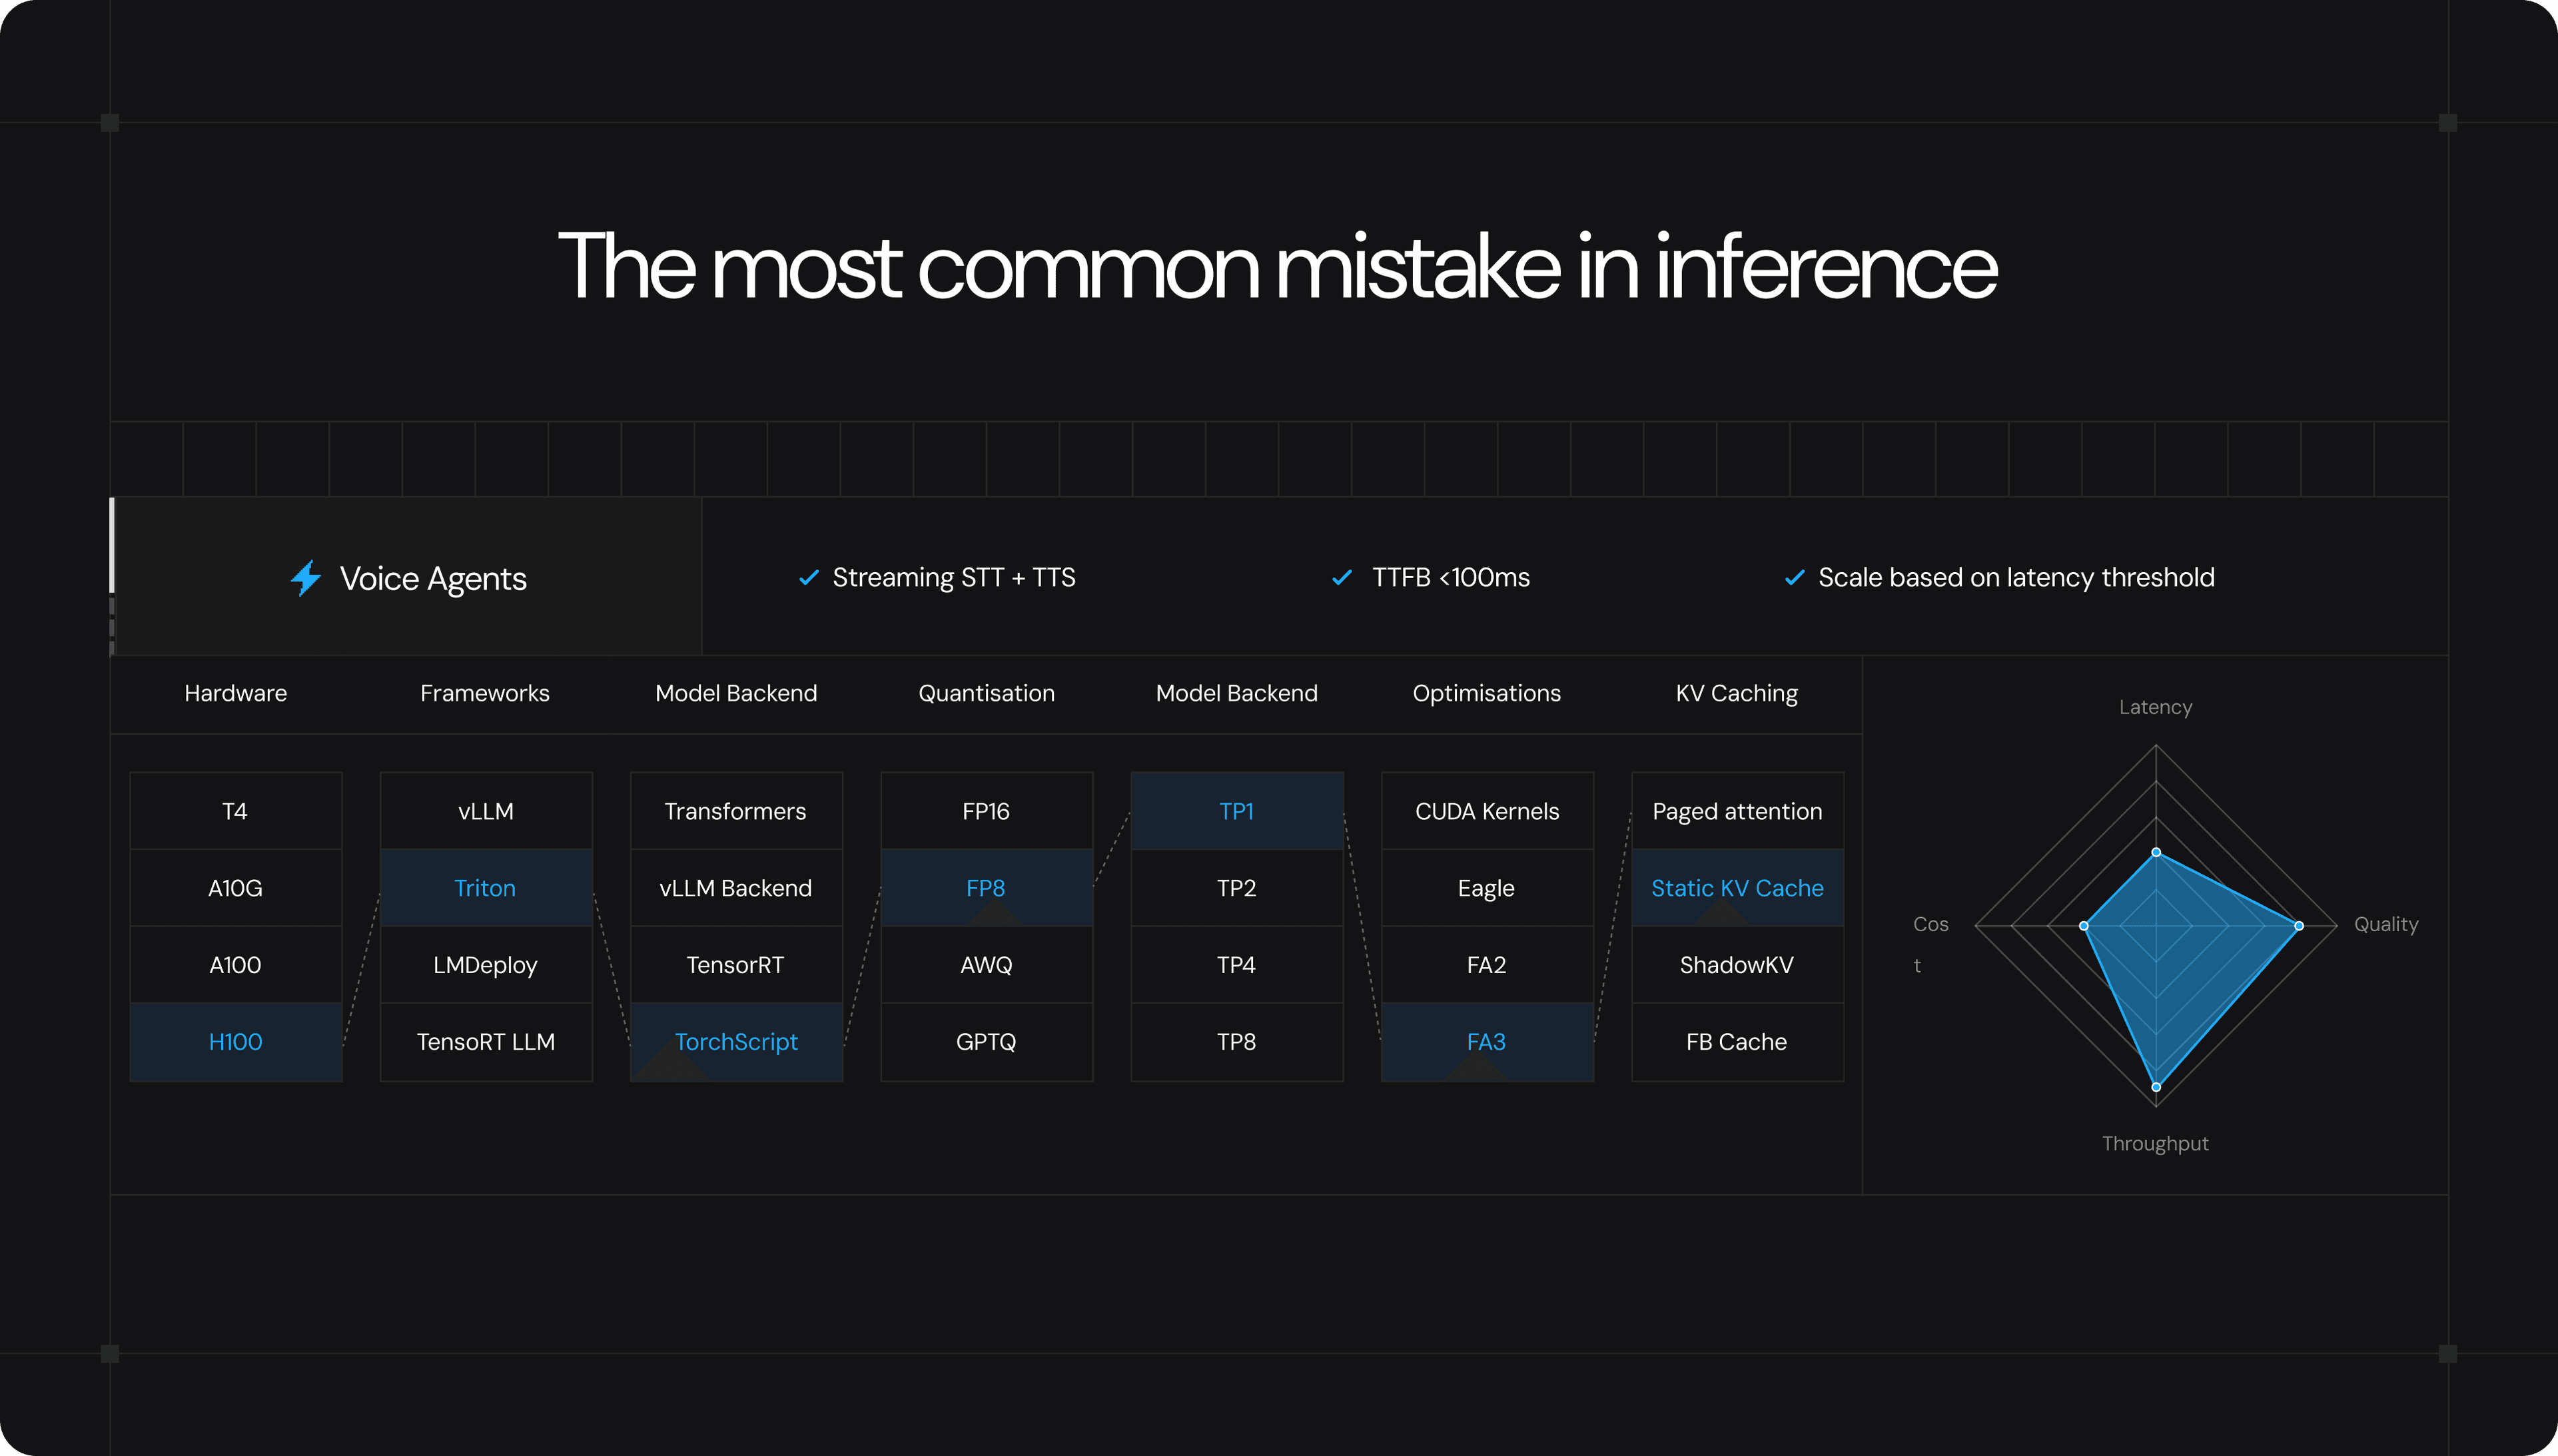
Making compiler-level breakthroughs visually legible
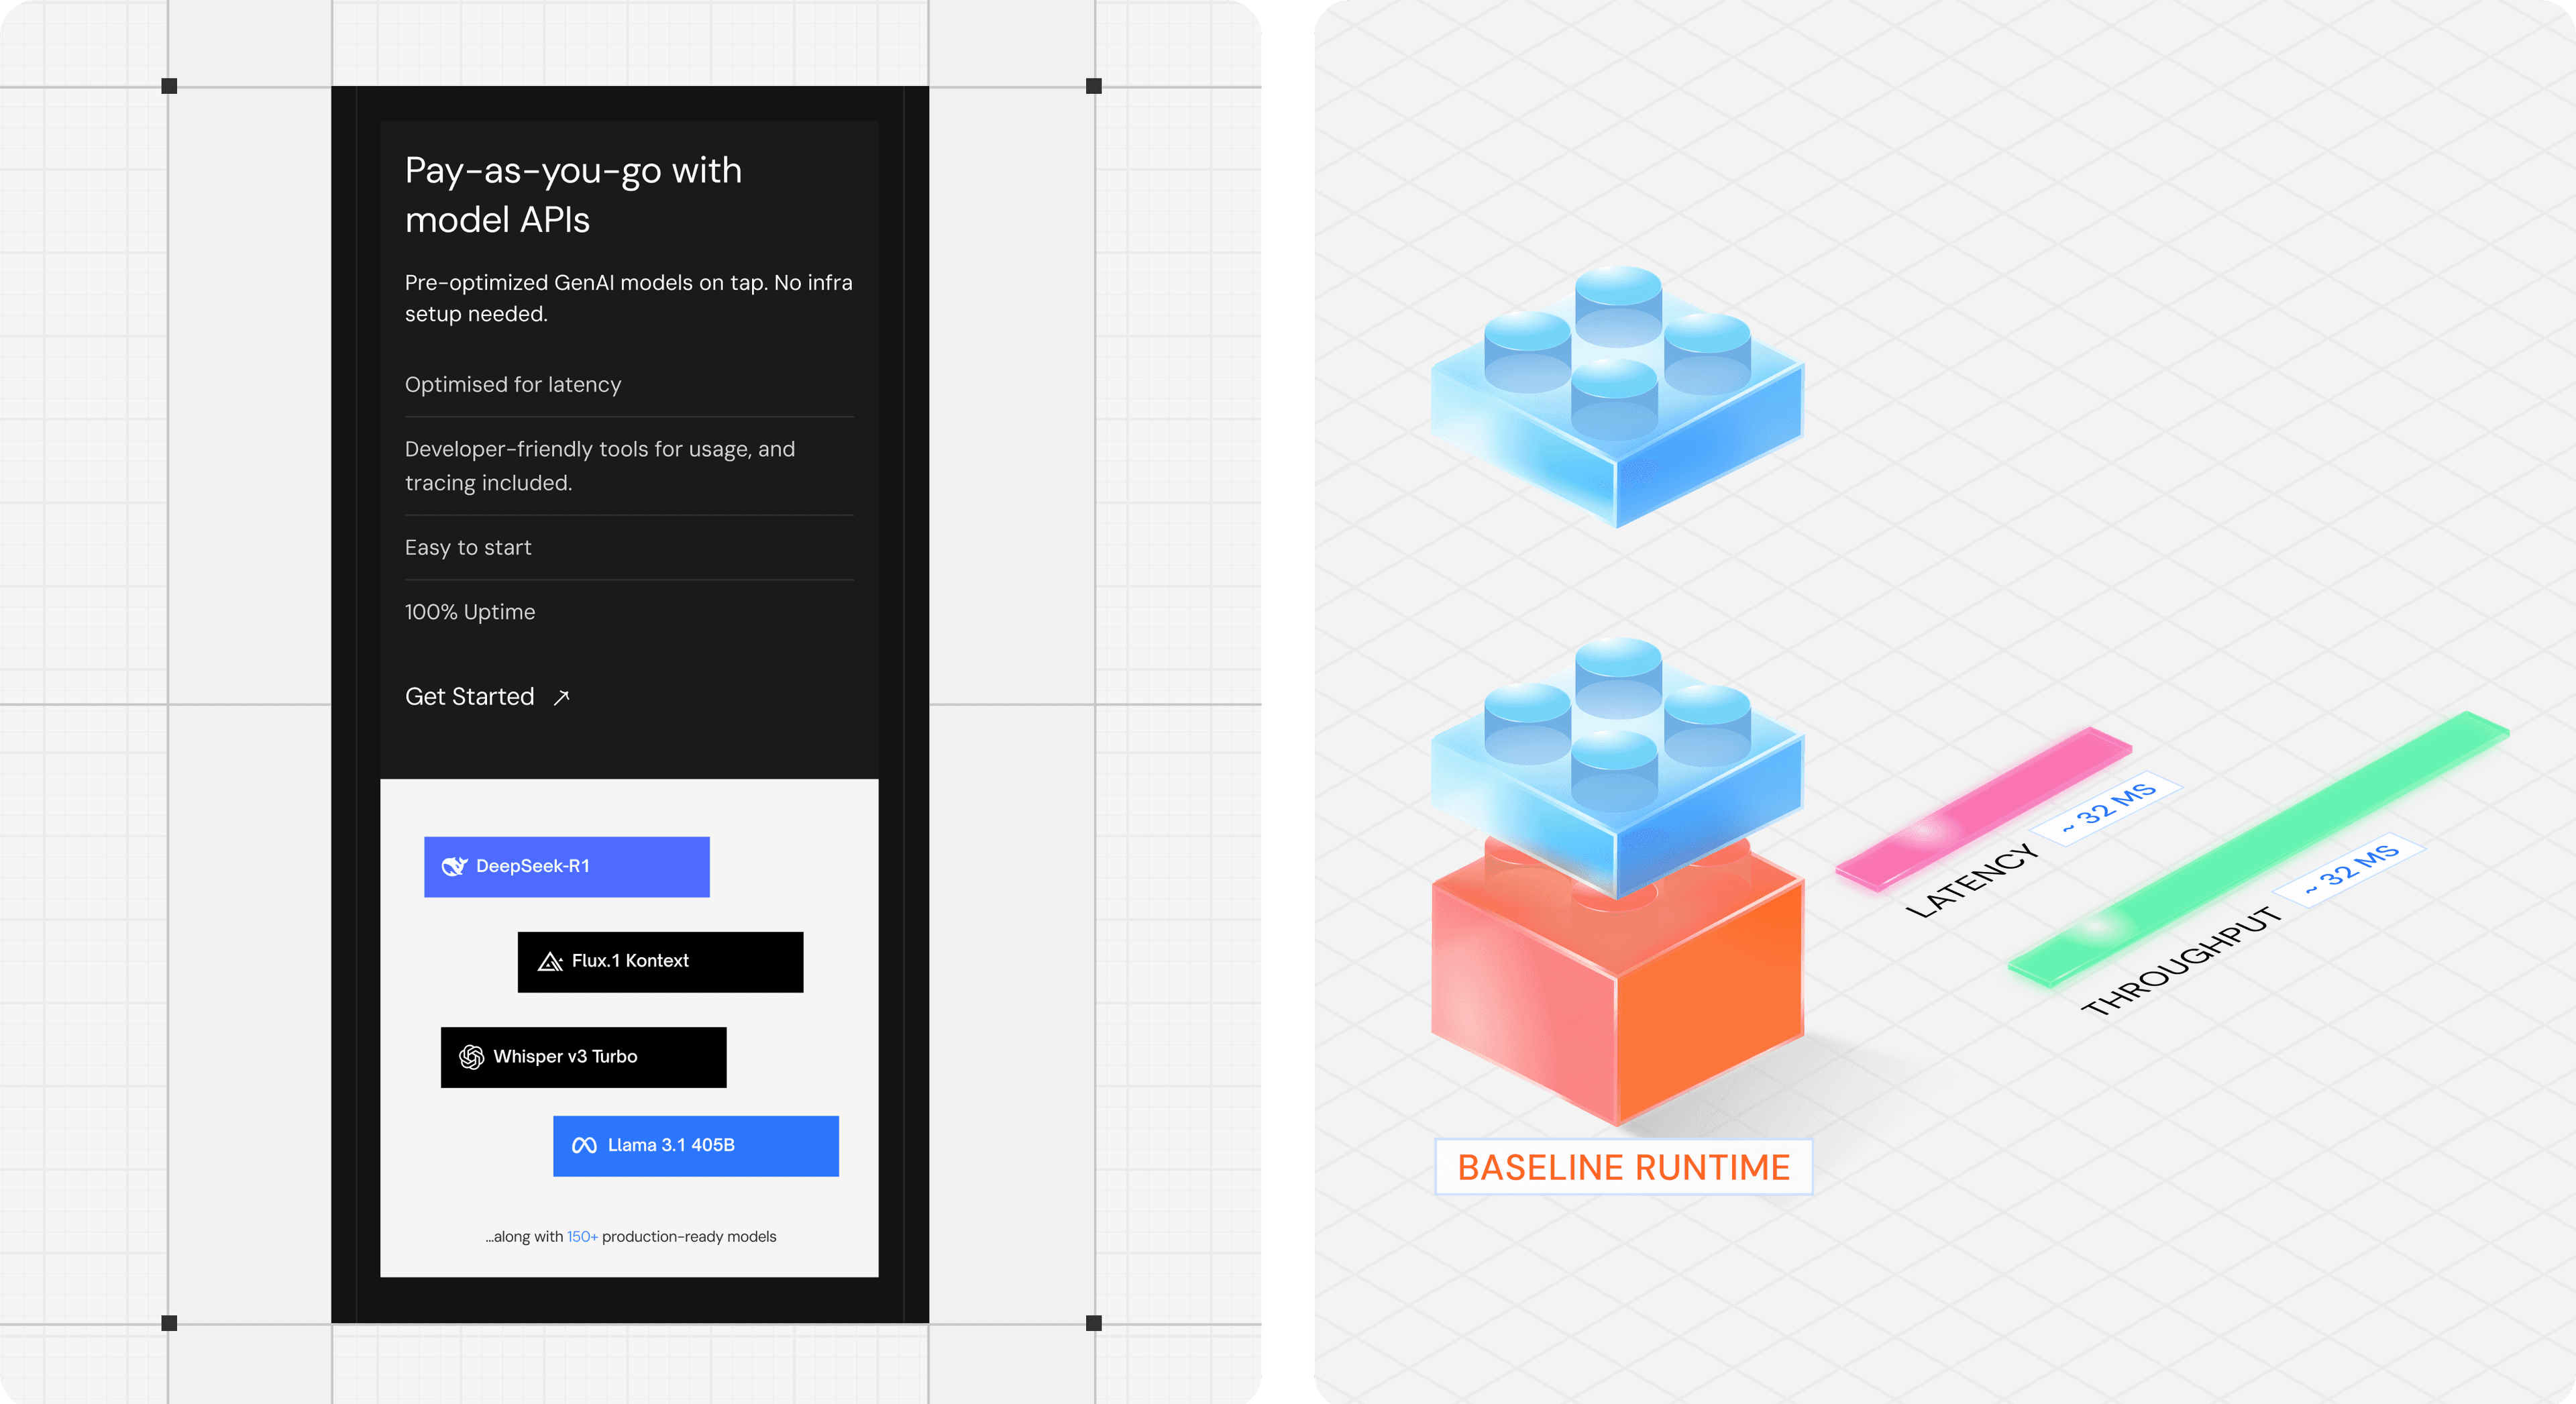
SimpliSmart's secret sauce isn't buying more GPUs; it's software-level optimization. Dynamic batching, kernel tuning, and memory allocation algorithms that squeeze maximum FLOPS out of NVIDIA H100 and A100 clusters.
We created an architectural diagram language that explains these complex systems at a glance, allowing infrastructure leads and CTOs to understand exactly why SimpliSmart can cut their inference cloud bill in half.
Software-optimized silicon
Eliminating GPU memory bottlenecks. SimpliSmart optimizes CUDA kernels and memory bandwidth, enabling models to serve concurrent traffic without latency degradation.
03Developer experience & brand system
Engineered for teams who live in terminal windows
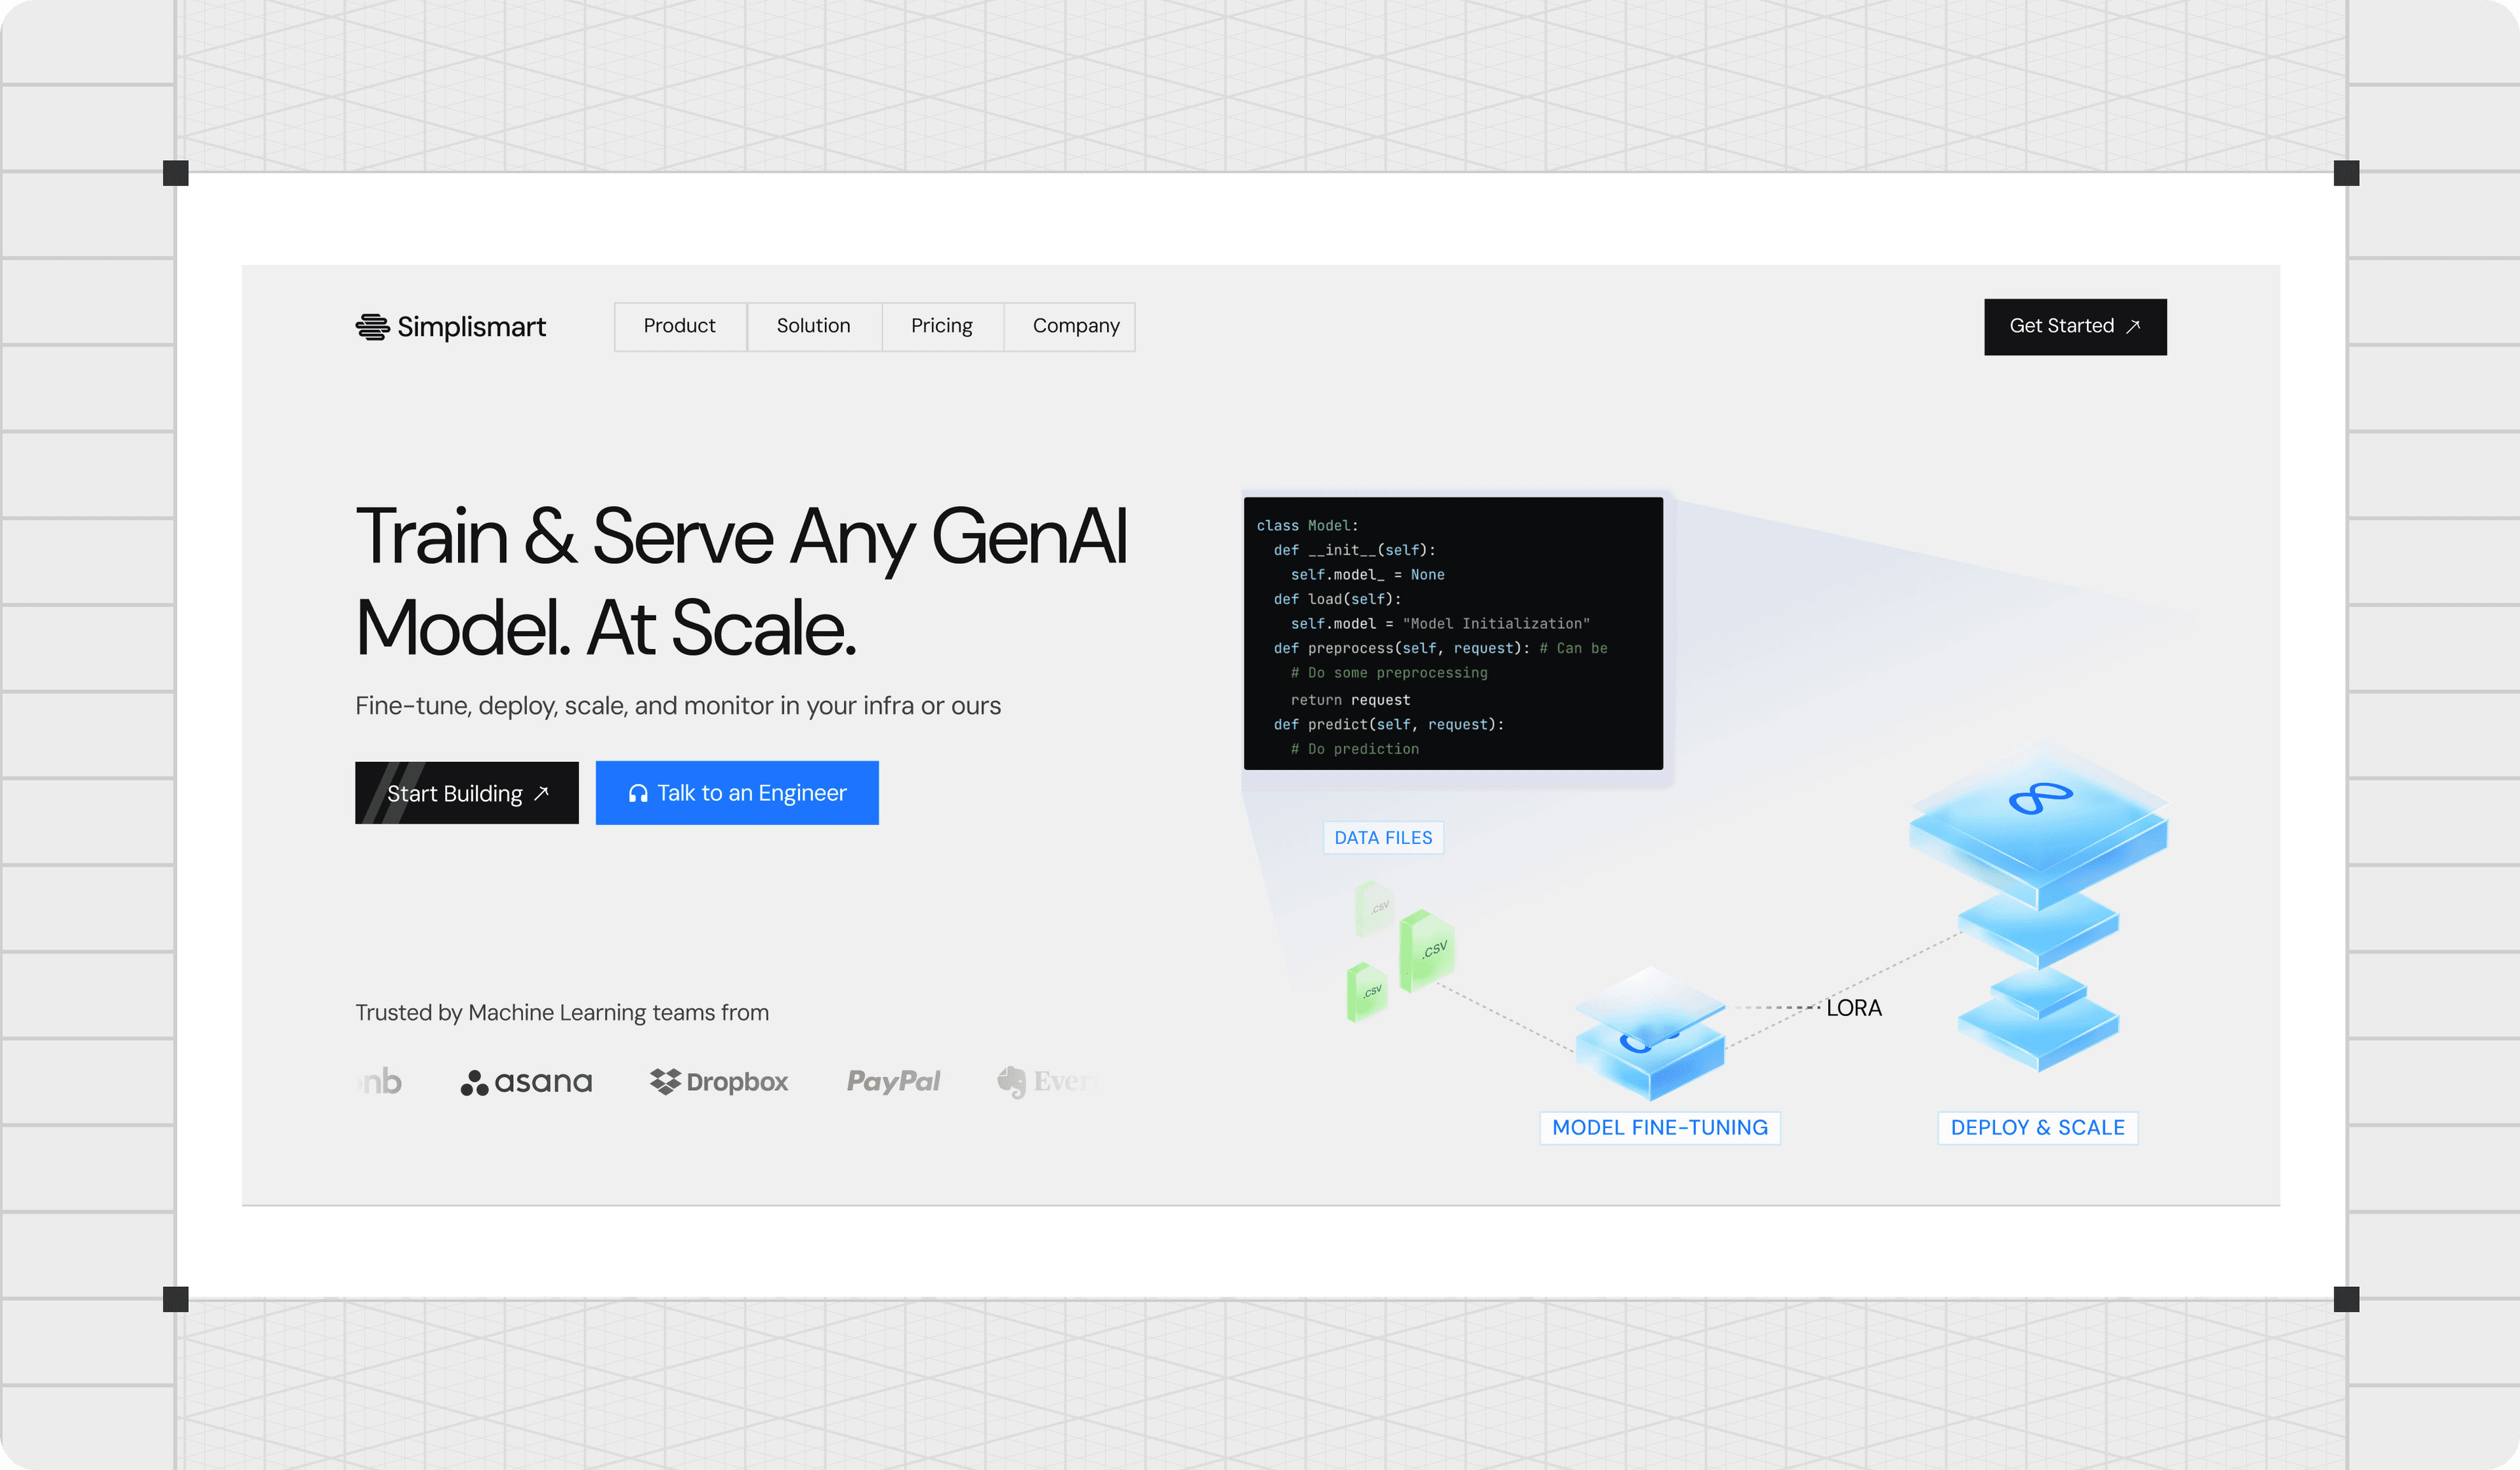
We built the brand around a technical cobalt and deep indigo palette, supported by crisp monospace typography and interactive code snippets. The Webflow landing page allows engineers to copy working Python commands, test latency endpoints, and preview deployment manifests instantly.
Custom technical motion demonstrates real-time token generation streams, illustrating how SimpliSmart's inference engine reduces time-to-first-token (TTFT) across large multimodal models.
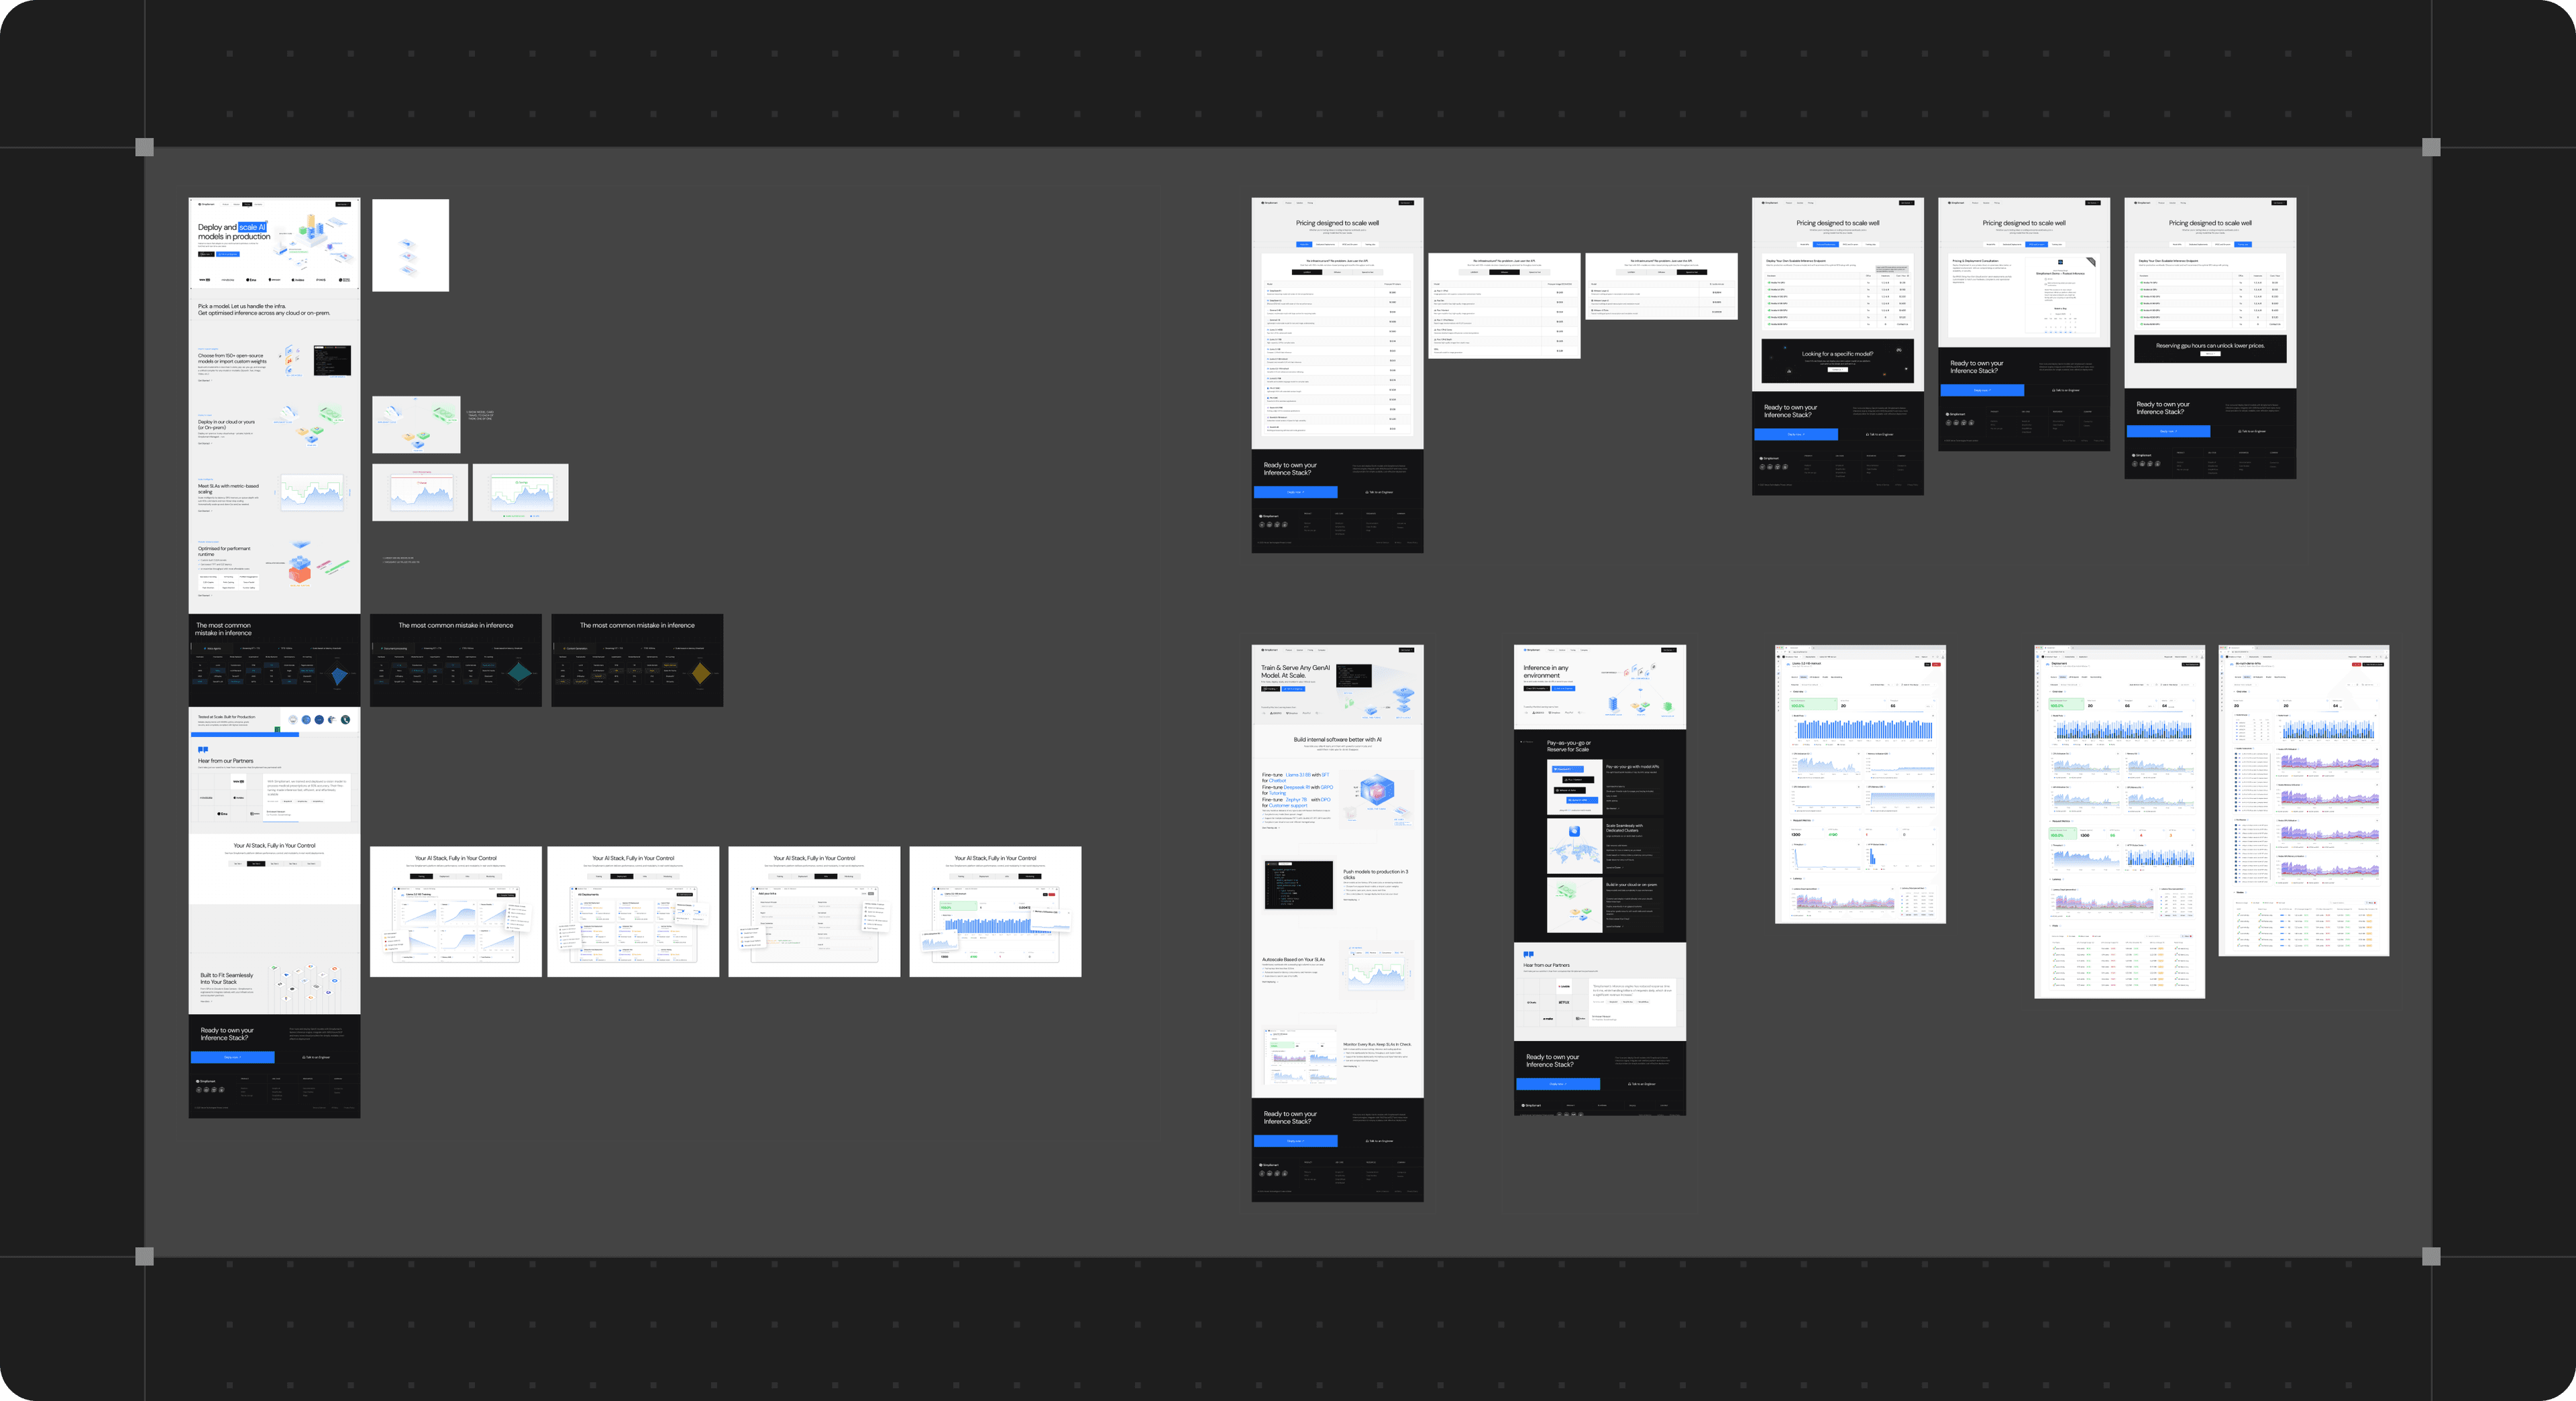
04Impact & proof
- 7M
- Series A led by Accel
- 30+
- Enterprise AI production customers
- ~$1M
- ARR reached shortly after launch
- <1ms
- Targeted inference latency speed
Performance and funding metrics reported following SimpliSmart's Series A announcement.
Brand Strategy
- Technical positioning
- Benchmark communication
- Developer messaging
Visual Identity
- Cobalt design tokens
- Monospace code styling
- Architecture diagram library
Webflow Development
- Interactive benchmark calculators
- Interactive code tabs
- Responsive layout
Motion
- Token streaming animations
- Latency comparison graphs
- Technical product teasers